The problem an AIOps platform should solve
Modern IT and network estates generate more events than any team can read. One underlying fault can set off hundreds of alerts across servers, links, applications and services, and the real issue is buried in the flood. Engineers burn out, on-call rotations become a grind, and customers notice the outage before the operations team finds its cause.
An AIOps platform earns its place when it changes that daily experience: fewer tickets, clearer priorities and a shorter path from alert to fix. That is the capability this page is about, whatever industry your operations team serves.
Alarm noise reduction that engineers trust
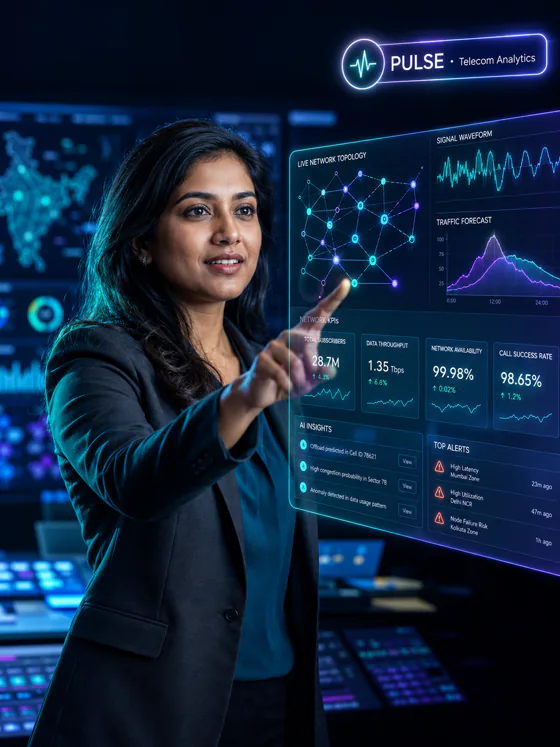
Humael Pulse is built to turn alarm noise into the incidents that matter. Instead of a wall of alerts, teams see a short list of incidents with the context they need to act. Engineers can see why events were grouped together and can correct the grouping, so the system earns trust rather than asking for it.
- A smaller, prioritised incident queue instead of raw alarms
- Context that shows likely impact on services and customers
- Clear reasoning your engineers can review and challenge
- A record of every recommendation and the decision taken
AI for IT and network operations, under human command
Pulse brings AI-native analytics to operations data from both the network and the business systems around it, so problems are seen in terms of their effect on service, not just on devices. It recommends next steps and, where your team allows it, carries out routine, low-risk actions. Anything that could affect customers or critical services waits for human approval.
This is how Hibilter approaches autonomous operations: automation grows step by step as confidence grows, and your team decides where the line sits. Every action is recorded, and changes are made in a way that can be reviewed afterwards.
For service desks, cloud operations, data centre teams and network operations centres alike, the result is the same: less time sorting alerts, clearer ownership of each incident and a calmer on-call rota. Leaders gain a clearer view of recurring problems, so investment goes to fixing root causes rather than adding more people to watch more screens.
Where GPU infrastructure is part of the estate
Many operations teams now also look after GPU clusters for AI workloads. Yantreal Prizm gives one source of truth and control over an entire GPU estate across cloud and on-premise, helping cut wasted GPU spend in a governed and reversible way, so infrastructure cost is managed with the same discipline as uptime.
How to get started with AIOps
We begin with a discovery session to understand your estate, your current tools and where noise hurts most. Next comes a private walkthrough on a sample of your own operational data, under NDA, so your engineers can compare the result with what they see today.
A pilot on one domain or service follows, with success measures agreed with your team. Once it proves itself, we help you scale across domains and gradually extend the actions your team is comfortable automating. Deployment can be managed cloud or on-premise.